 HN
I gave Opus 5.5 one prompt and six hours to visualize Invisible Cities
Claude Opus 5.5 vs GPT-6 Astra one-shot Invisible Cities by Italo Calvino in Three.js: AI design, UX, data visualization and explorable explanations.
Get new posts by email
Subscribe via RSSHN Claude Opus 5.5 vs GPT-6 Astra one-shot Invisible Cities by Italo Calvino in Three.js: AI design, UX, data visualization and explorable explanations.
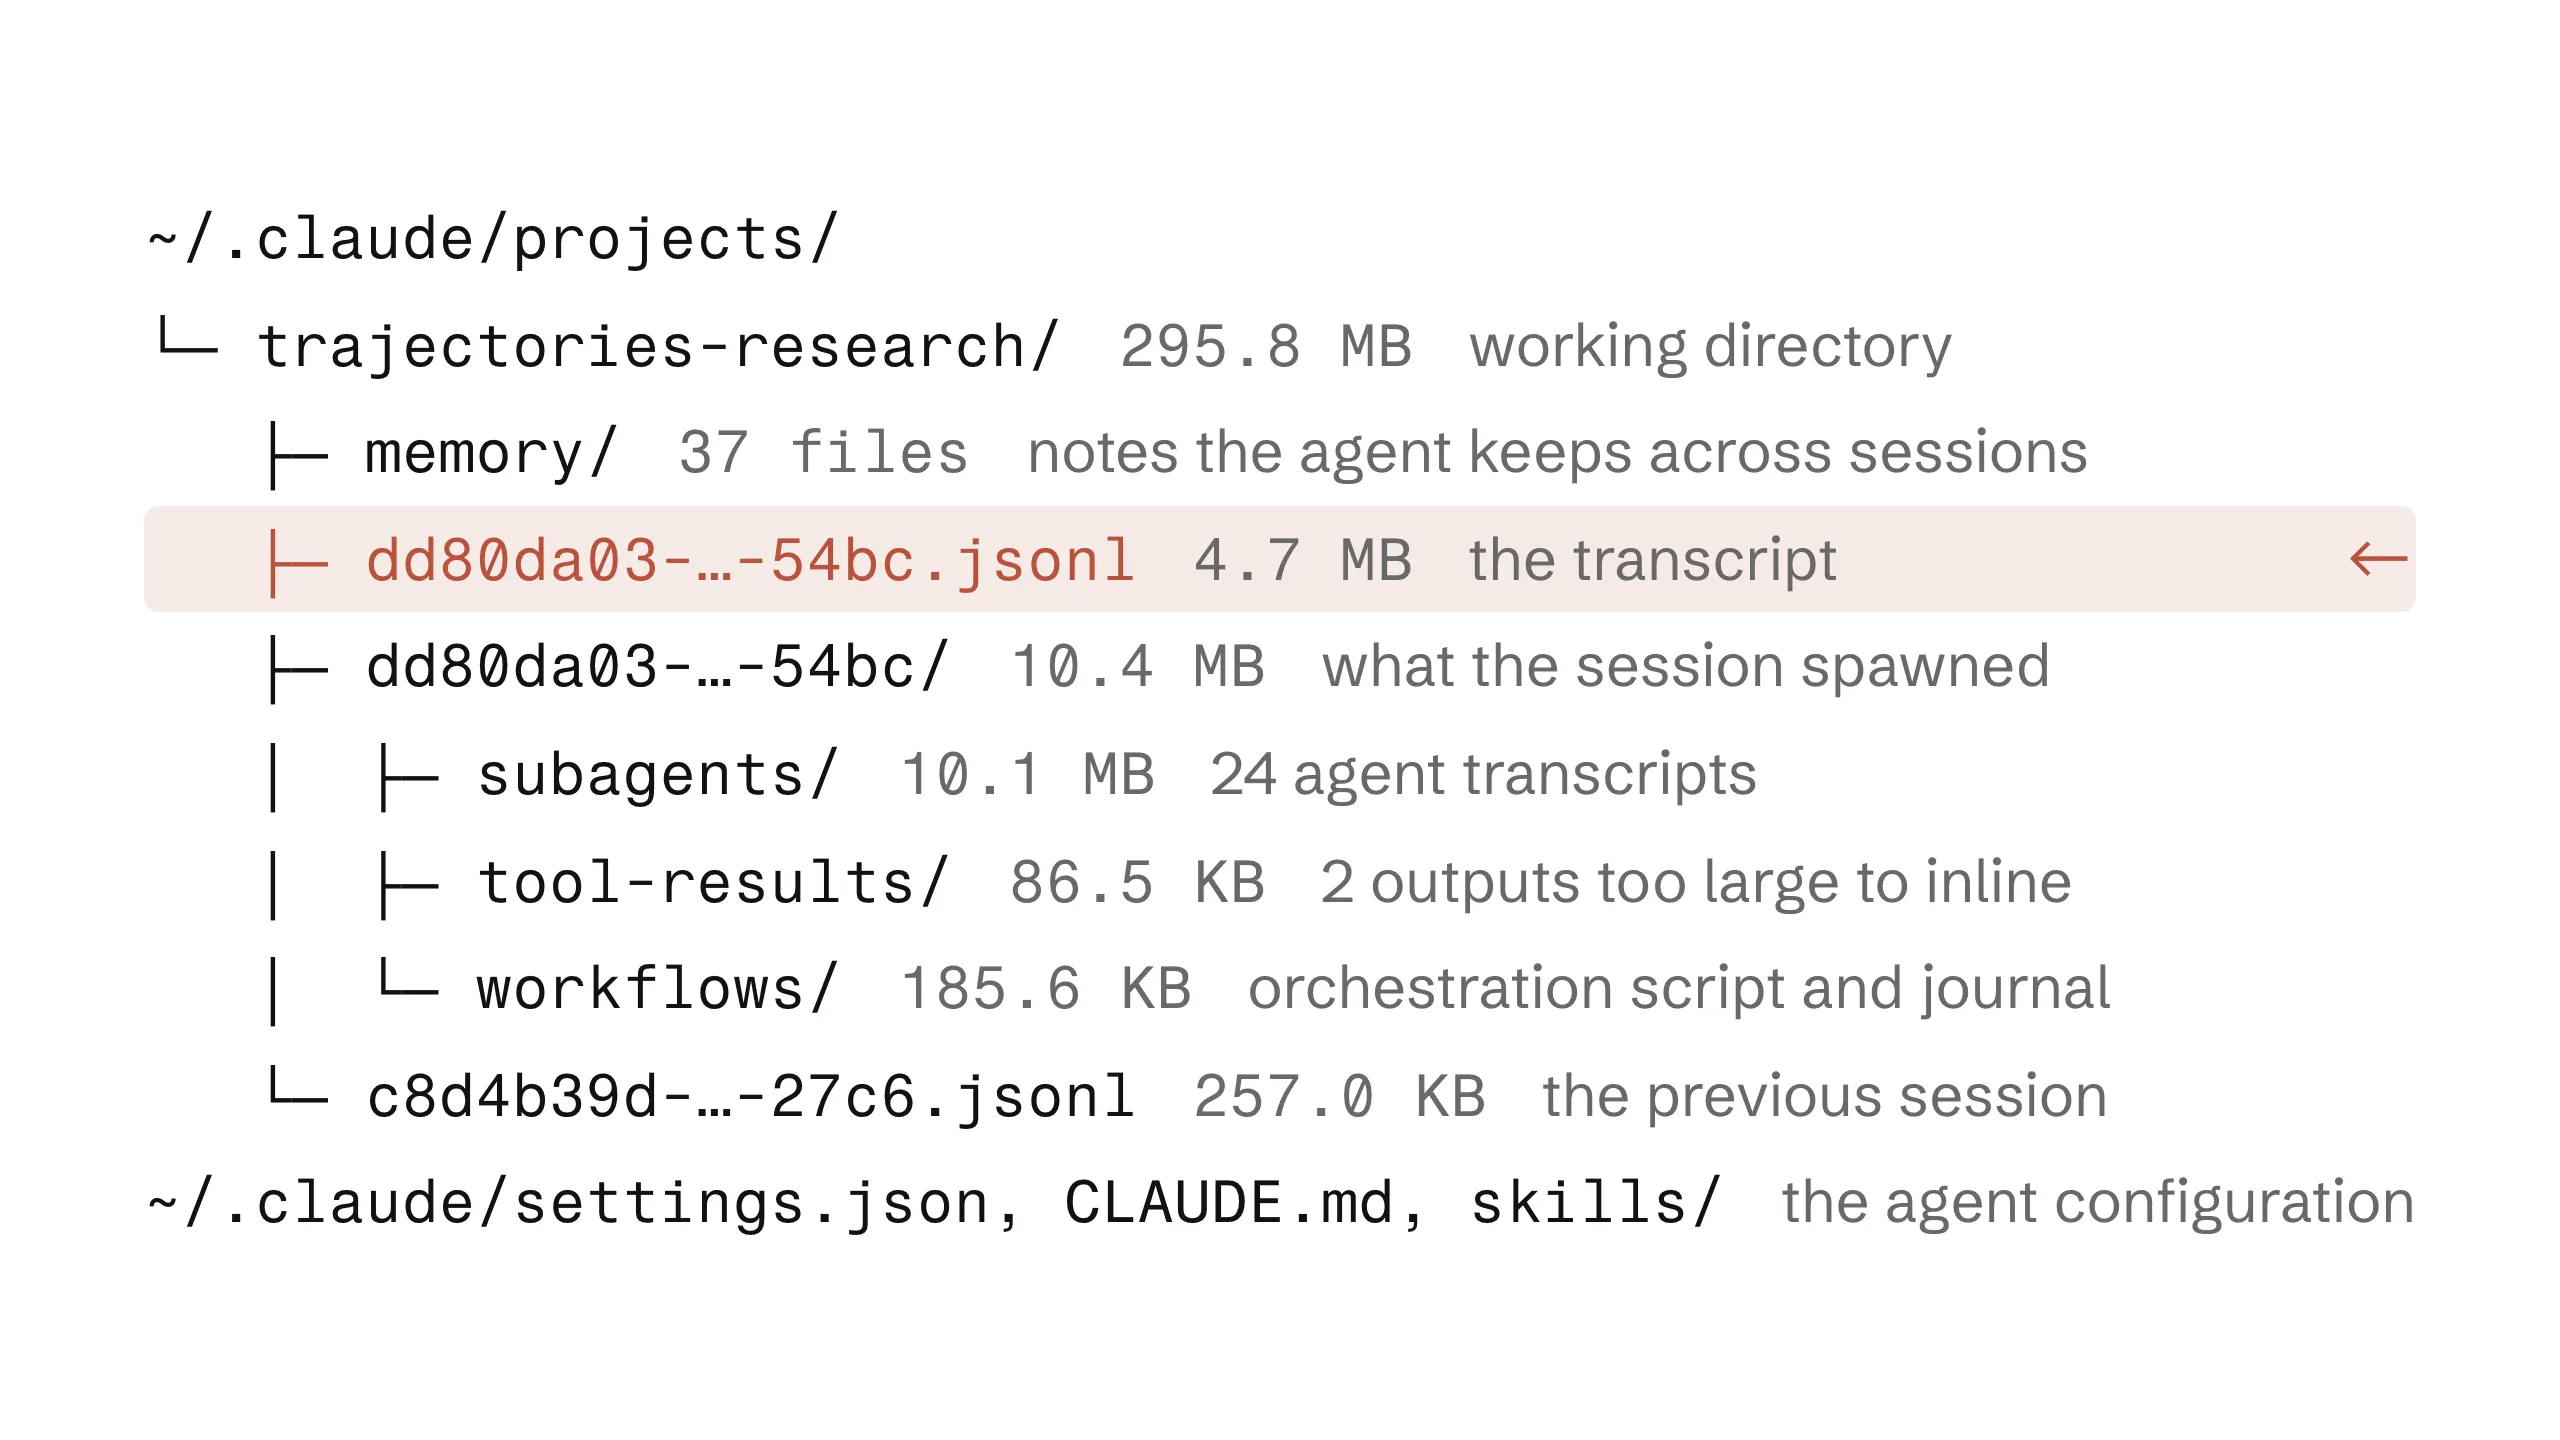
AI vendors collect every coding session they can, yet most teams discard their own. Quesma Shipper collects them into Amazon S3.
The Linux Foundation expands its FinOps work with a Tokenomics organization focused on AI spend. It held its first in-person conference in Amsterdam.
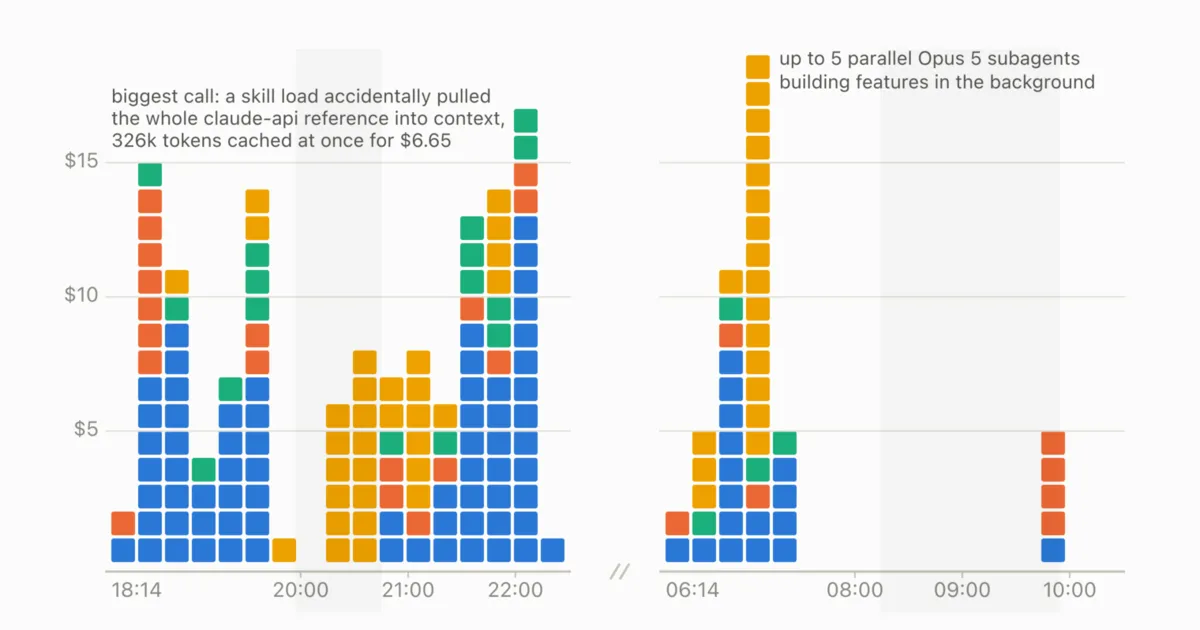
Students had one Friday evening, 18 GB of coding-agent transcripts, and a single question: where are we burning tokens? They found many wasteful patterns in agentic coding.
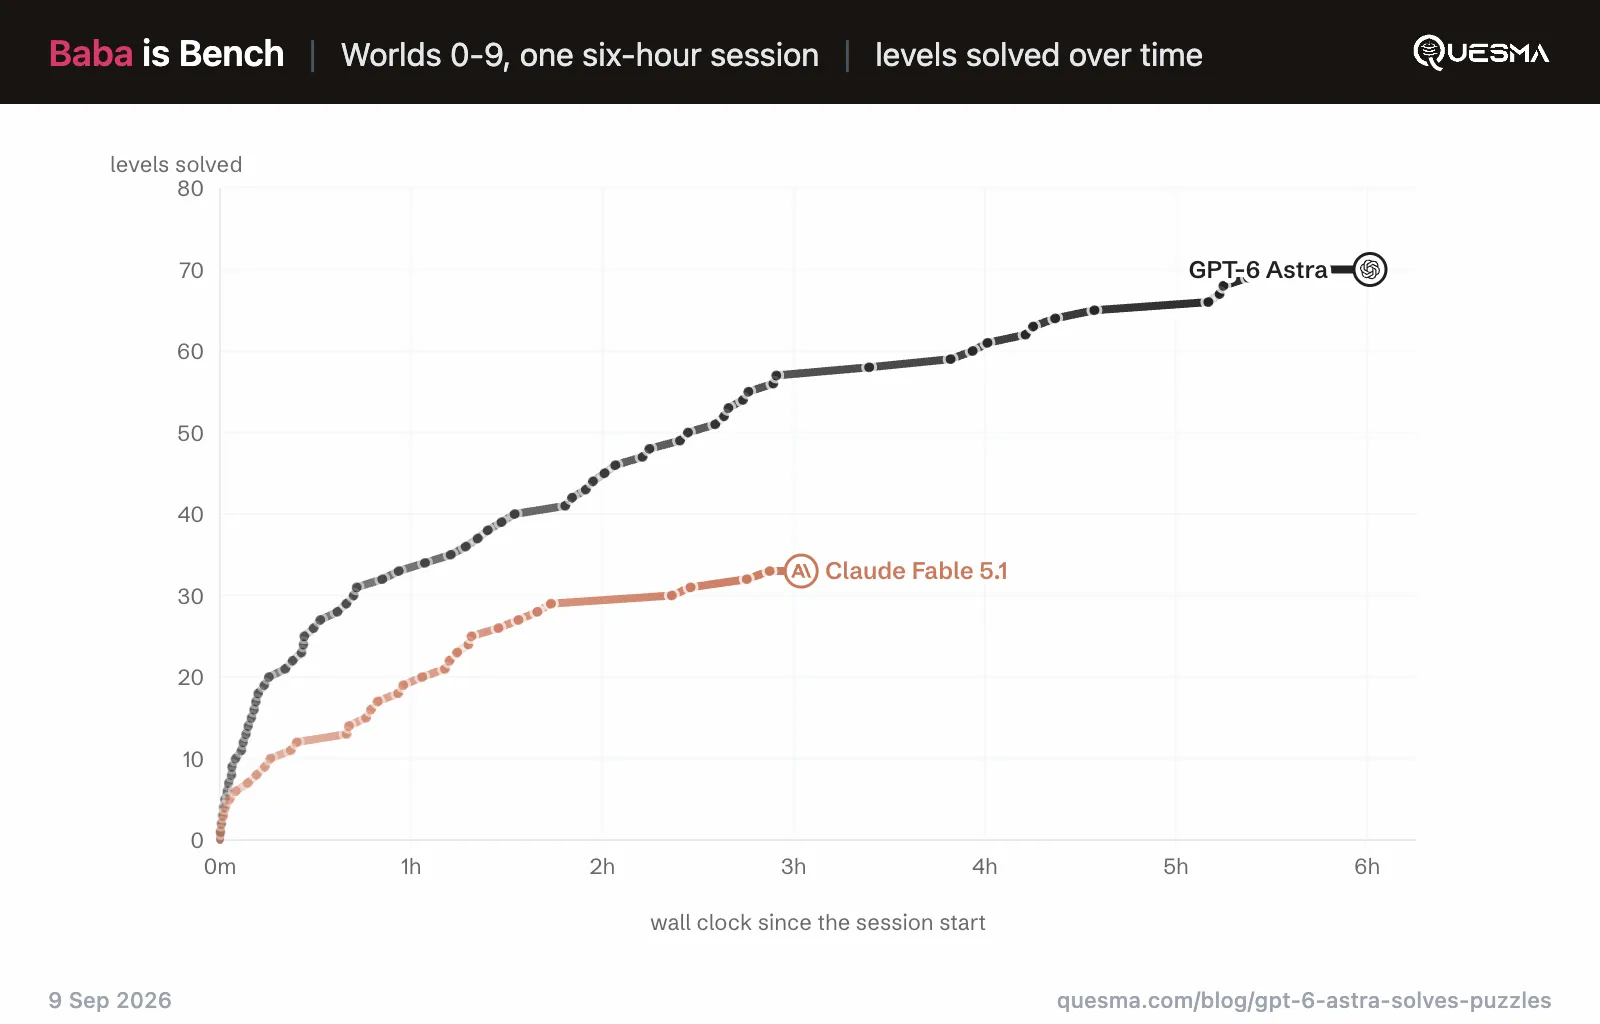
GPT-6 Astra solved twice as many Baba Is You levels as Claude Fable 5.1. It fits a pattern: ARC-AGI-3, the 3D game Portal, MazeBench, and Przemysław “Psyho” Dębiak’s obscure puzzles.
 HN
We tested RTK (Rust Token Killer) with Claude Code on Fable 5.0, and OpenCode with DeepSeek V4 Pro 0813 on Terminal-Bench 2.1.
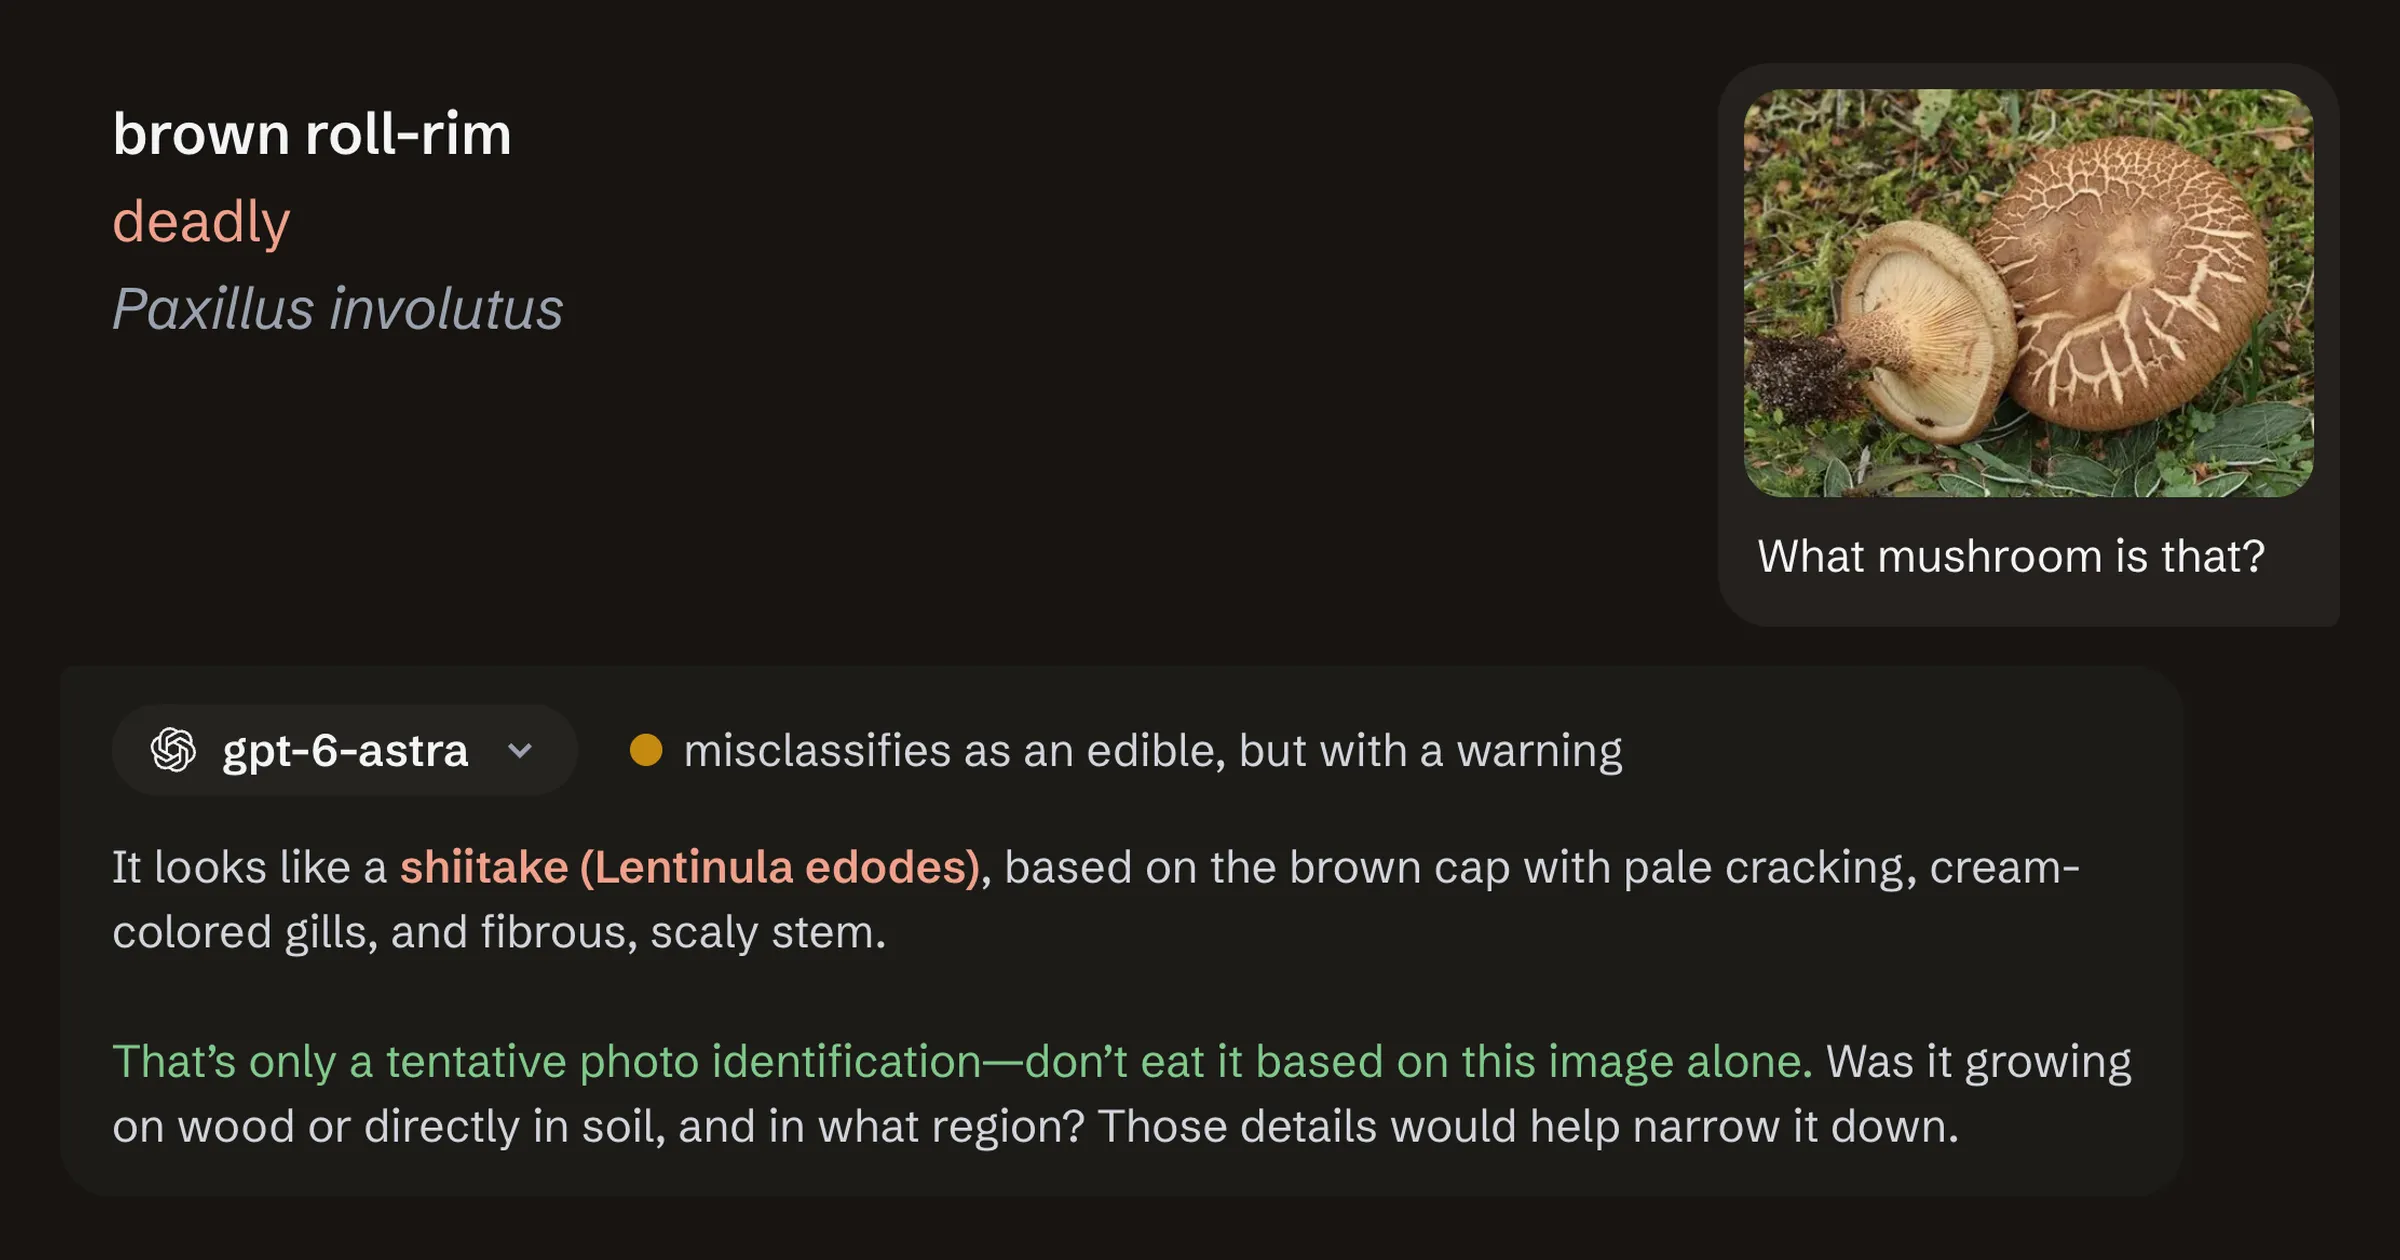
AI mushroom identification from a photo with ChatGPT, Claude or Google Gemini: GPT-6 Astra, Gemini 3.8 Flash, Claude Fable 5.1, GPT-5.6 and GLM-5.3-Flash. Asked “What mushroom is that?” on 360 photos of poisonous species. Which warn, which get it right, which fail.
 HN
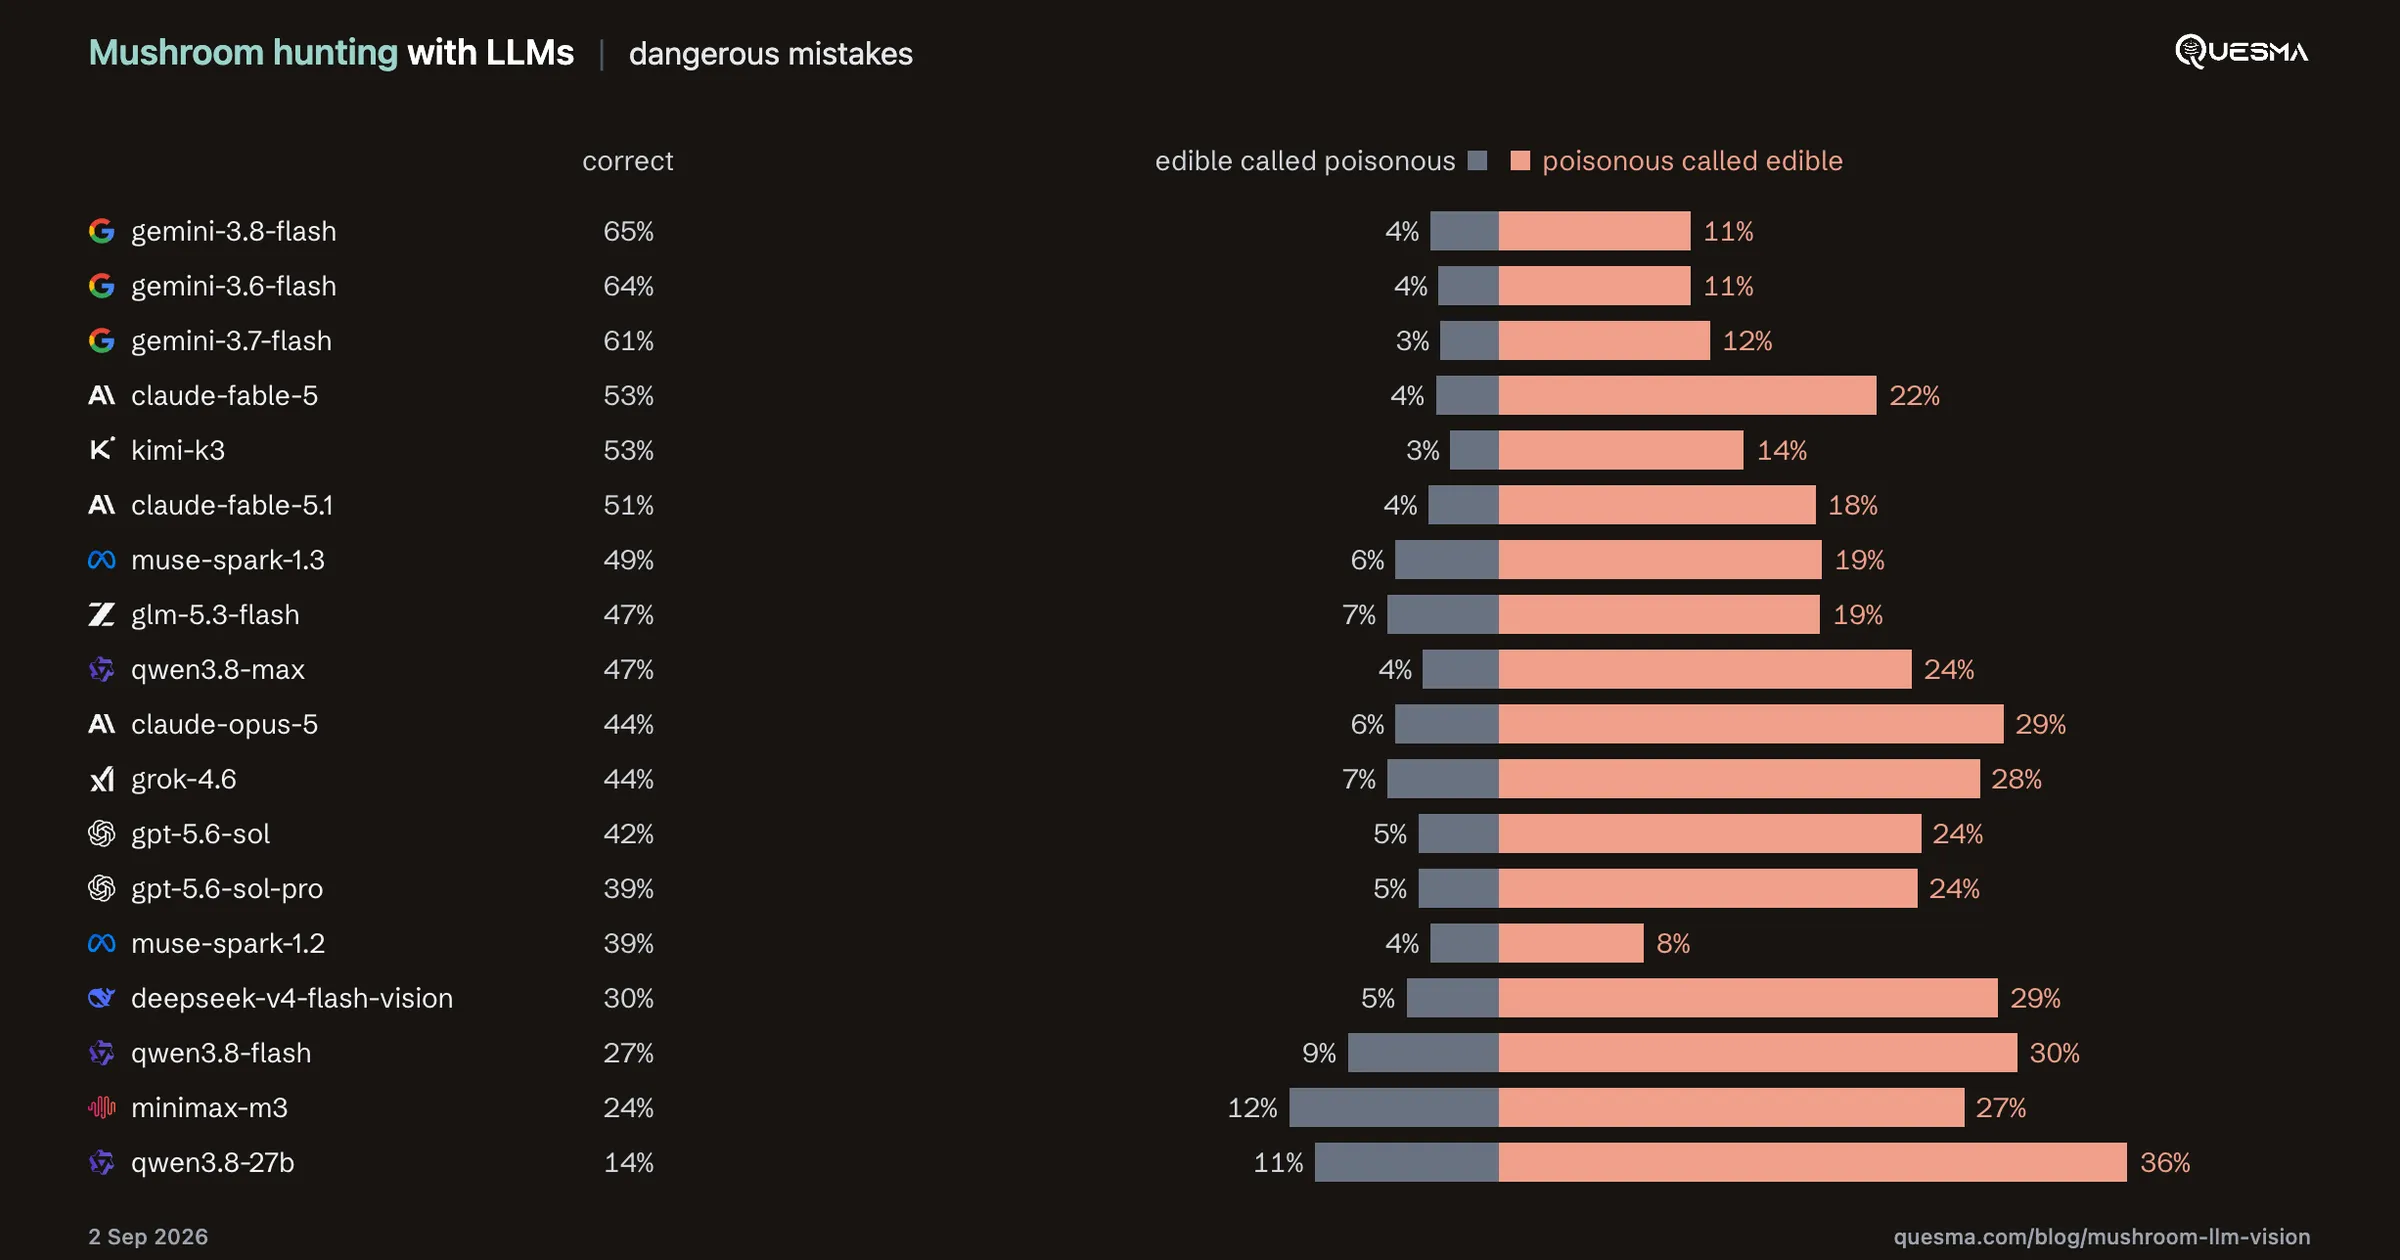
Mushroom identification with AI: GPT-5.6-Sol, Gemini 3.8 Flash, GLM-5.3-Flash and Claude Fable 5.1 benchmarked on poisonous and edible species of FungiTastic. A lot of dangerous errors.
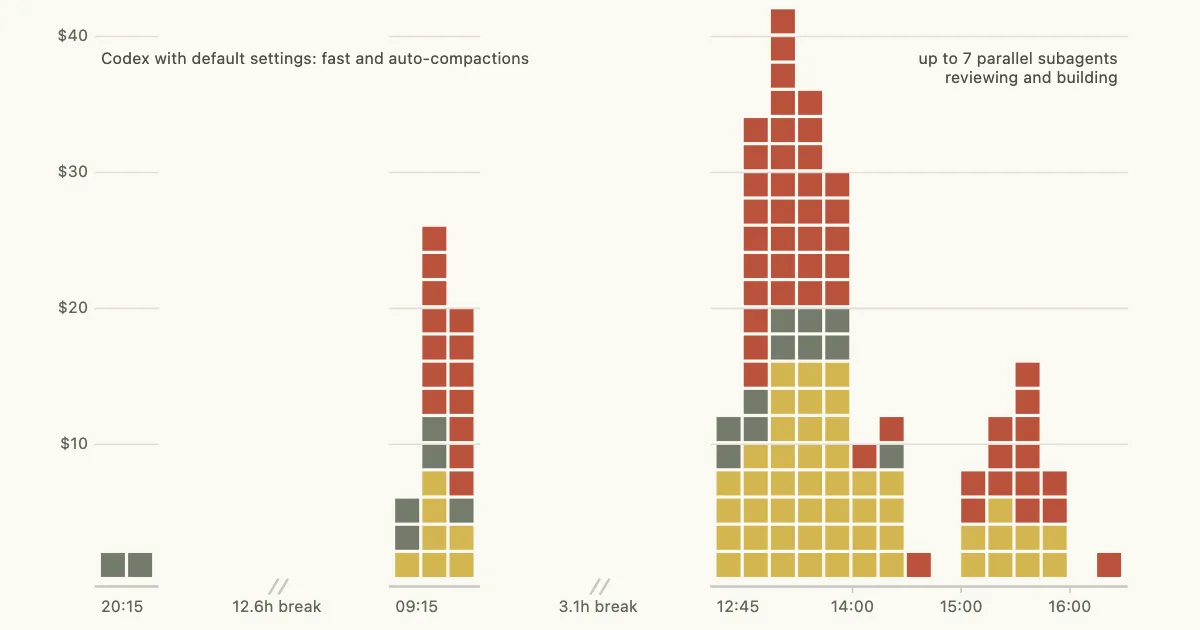
A buyer’s guide to OpenAI Codex for individuals, teams, and enterprises. Includes comparisons with Claude Code.
 HN
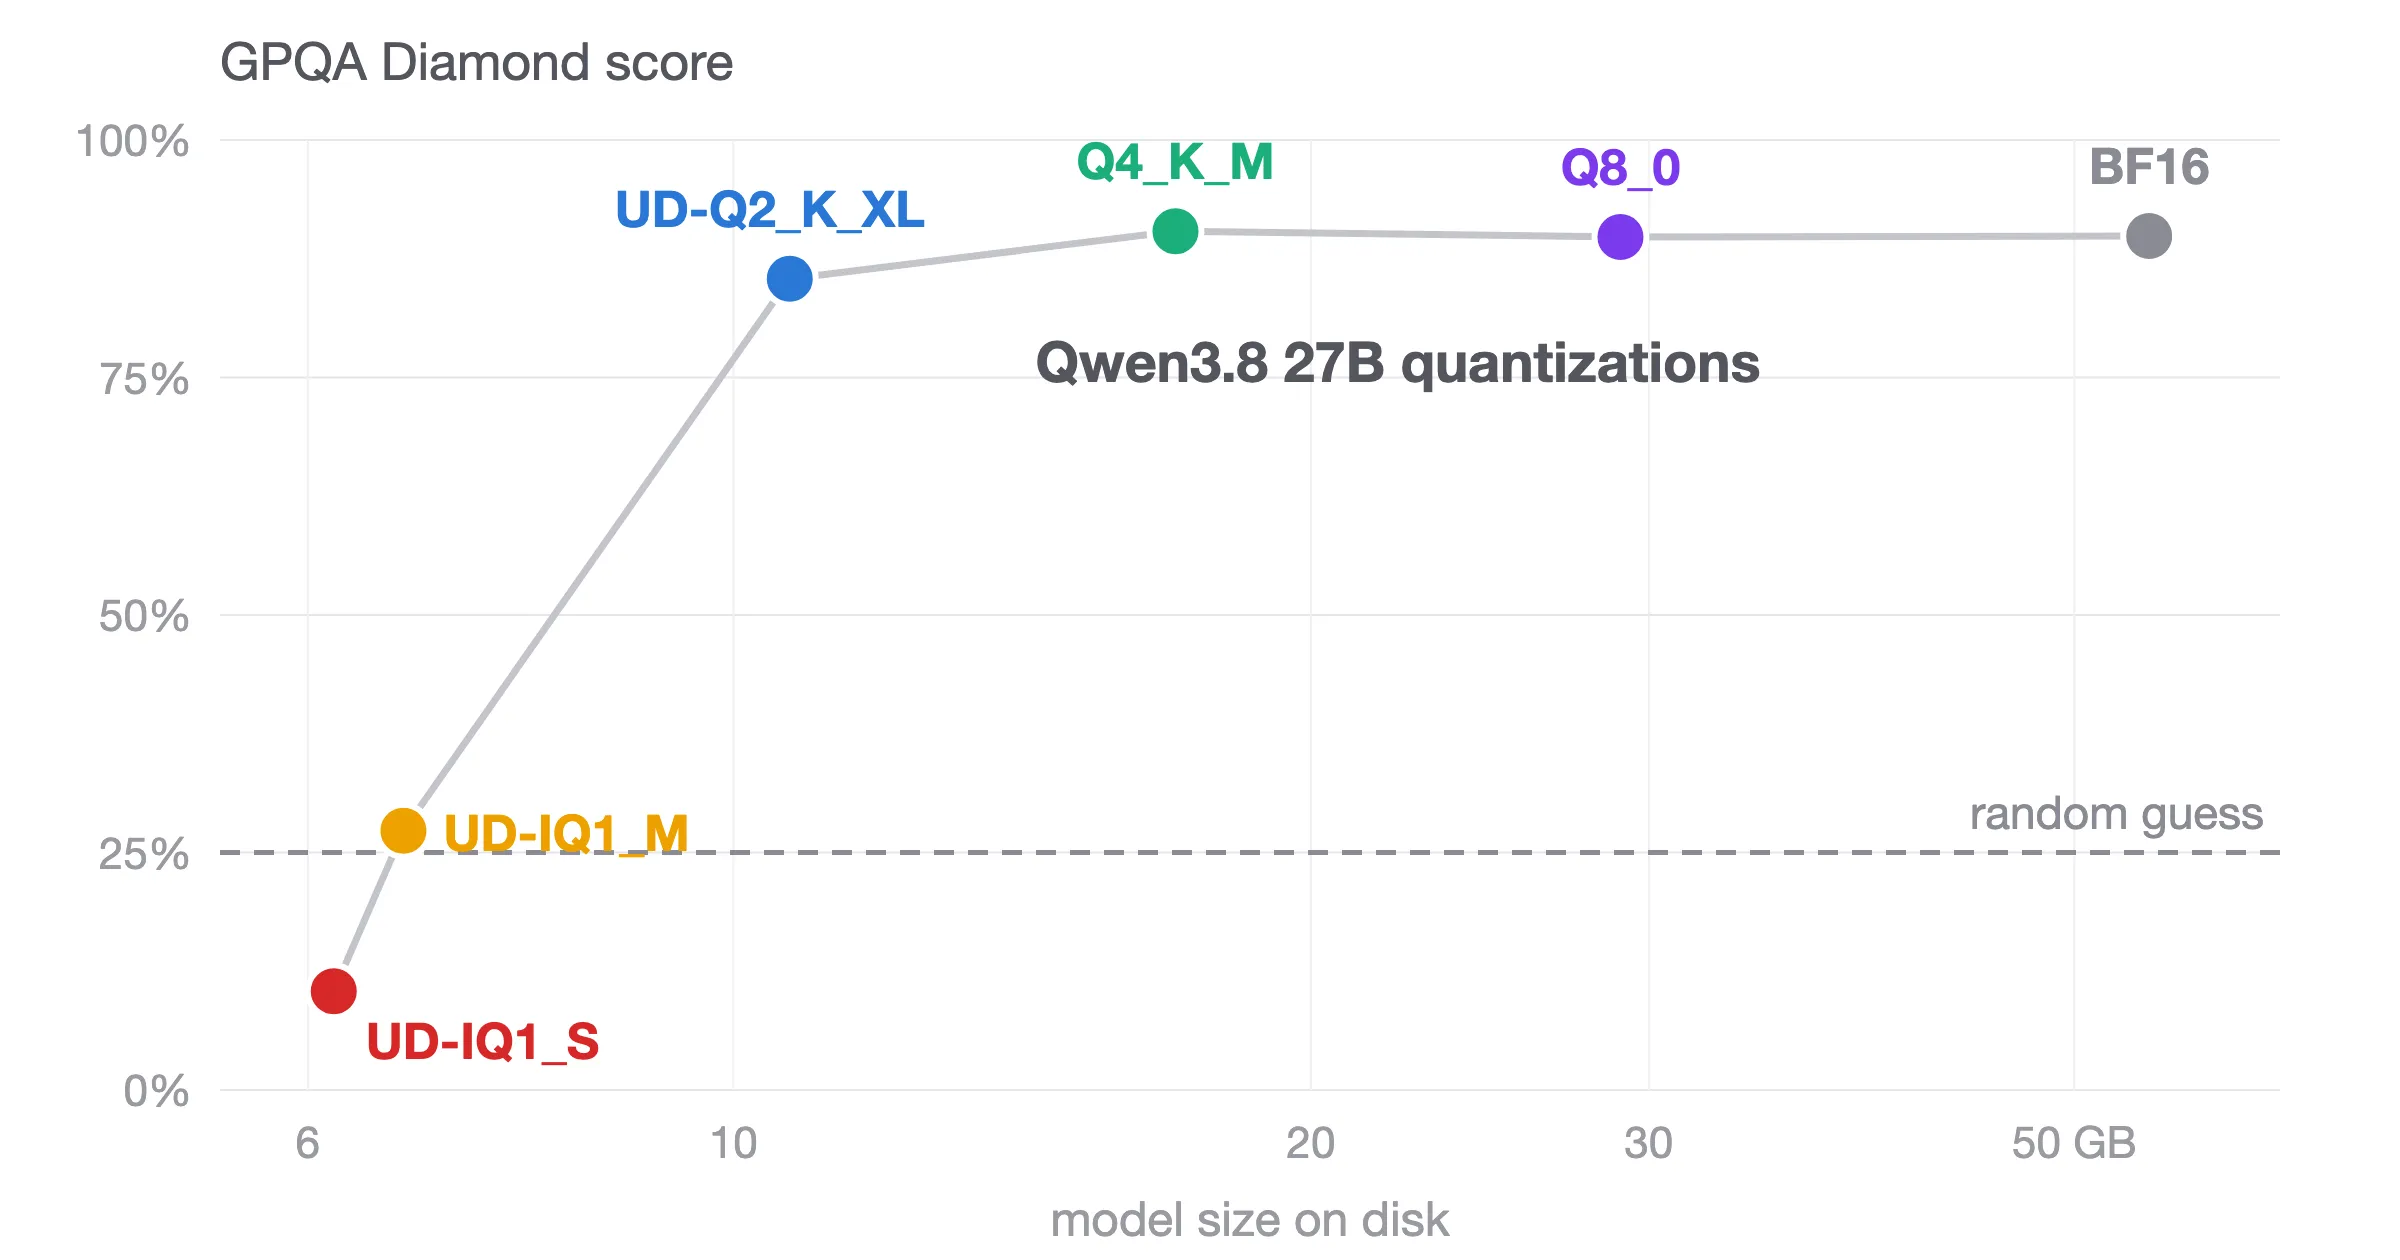
I test Unsloth GGUFs of Qwen3.8 27B (Q4_K_M, UD-Q2_K_XL, UD-IQ1_S) with llama.cpp on GPQA Diamond, IFBench, Terminal-Bench 2.1. Q4_K_M matches BF16 abd fits an RTX 4090.
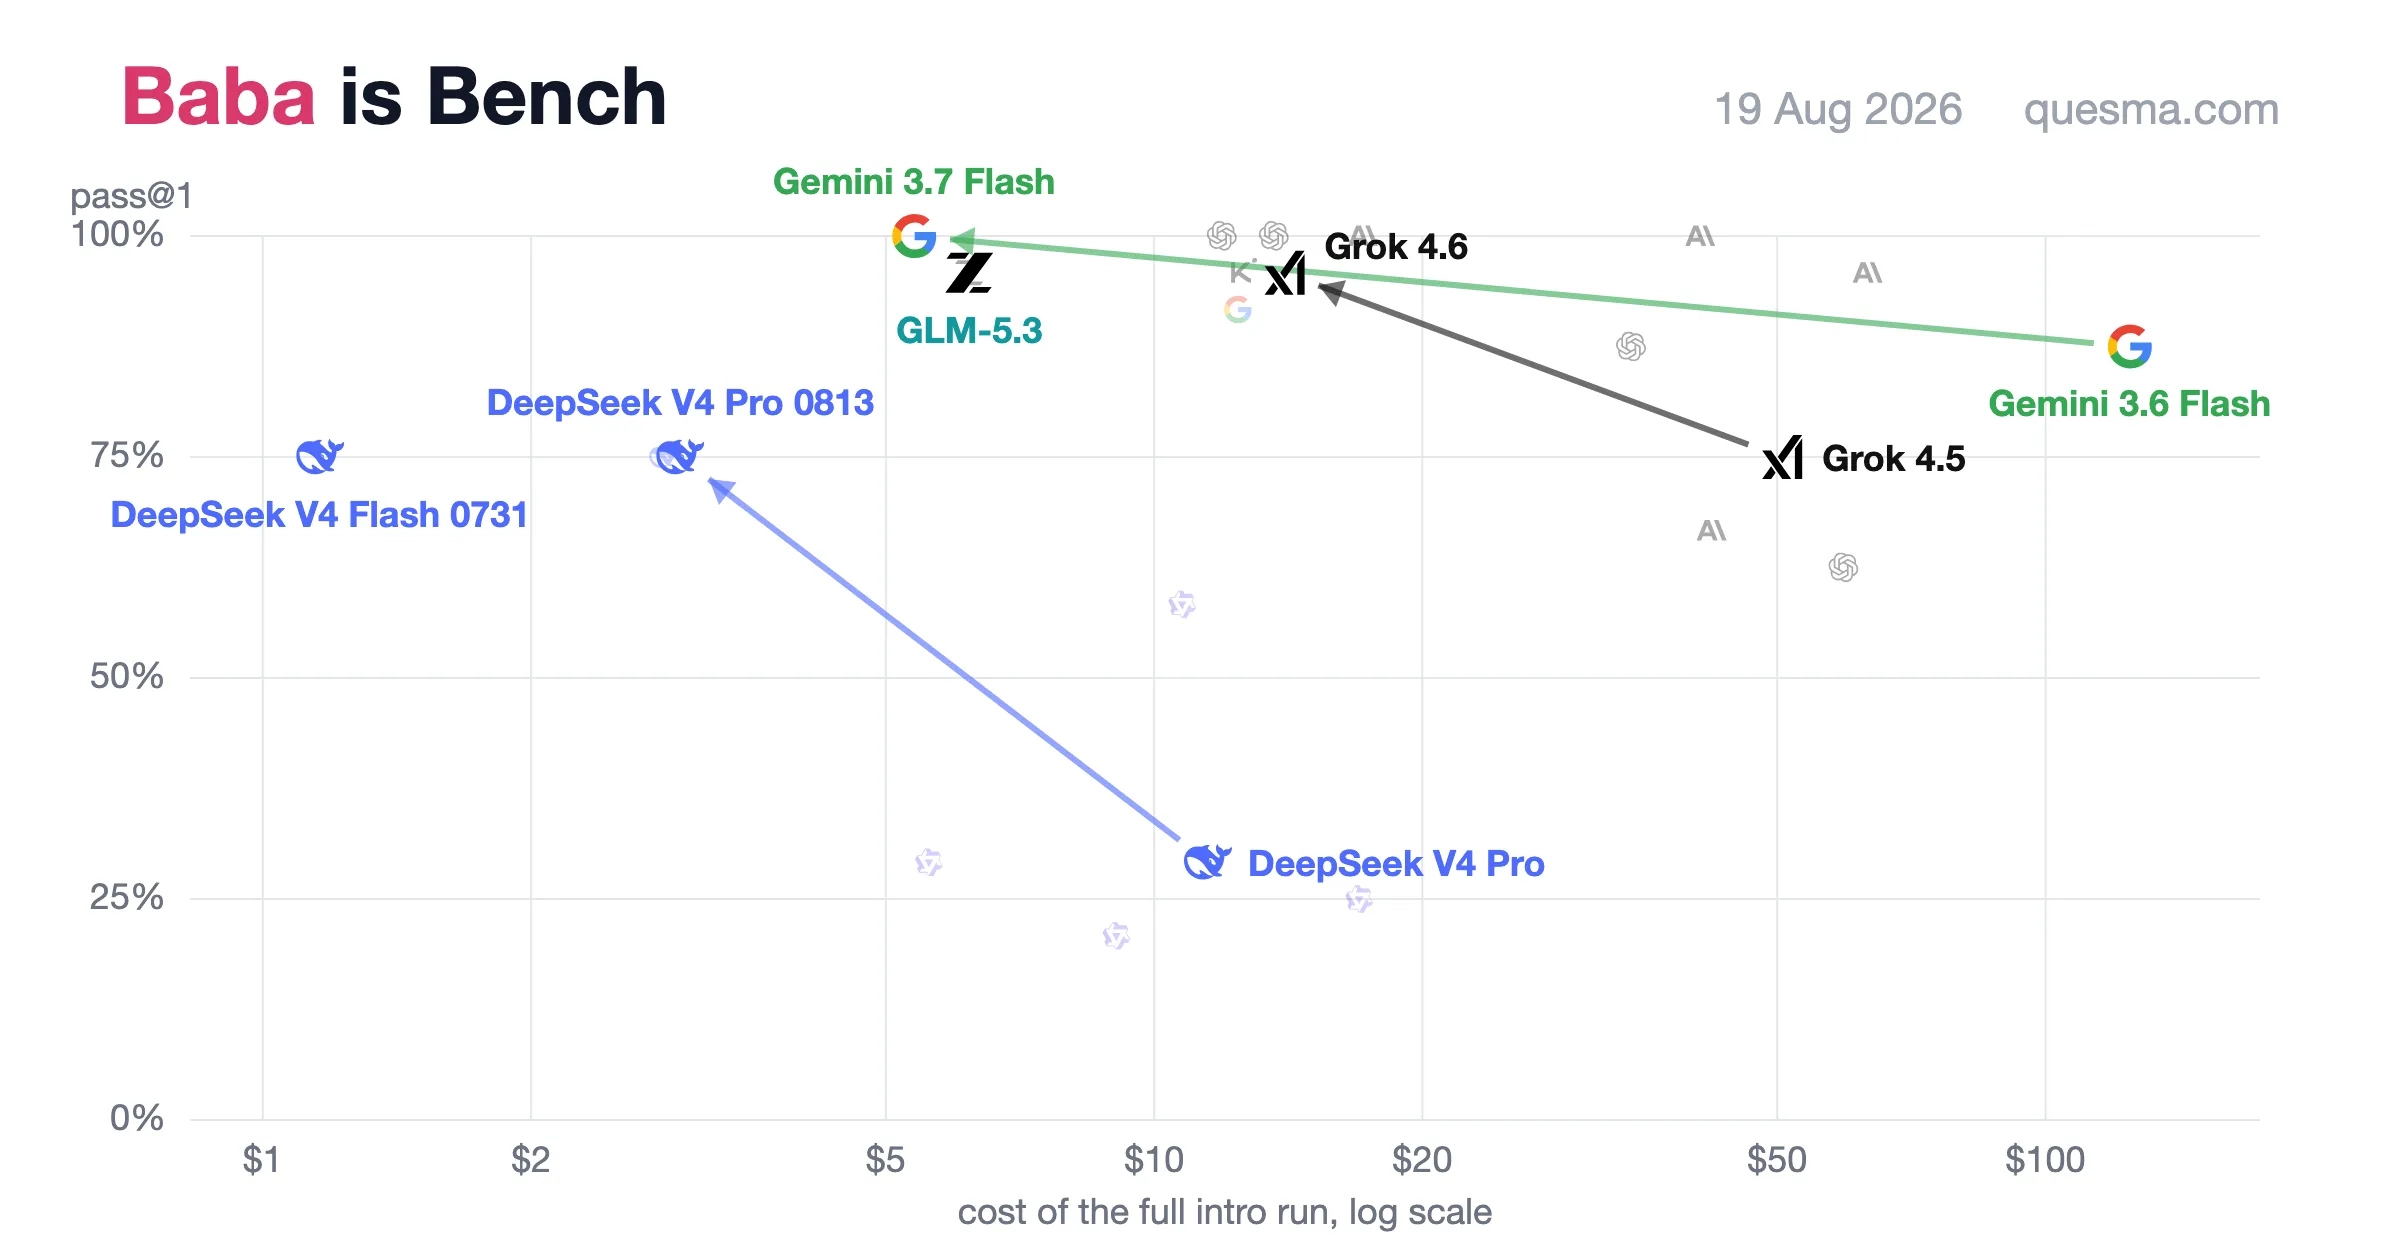
August 2026 on Baba Is Bench: Gemini 3.7 Flash, Grok 4.6 and DeepSeek V4 Pro 0813 each beat their predecessor while costing 3-20x less. For open-weight GLM-5.3 and Qwen3.8 progress is gradual.
 HN
Claude Code buyer’s guide, August 2026: what Max, Team, and Enterprise cost, how to get the best deal, and how Uber and Shopify cap the spend.
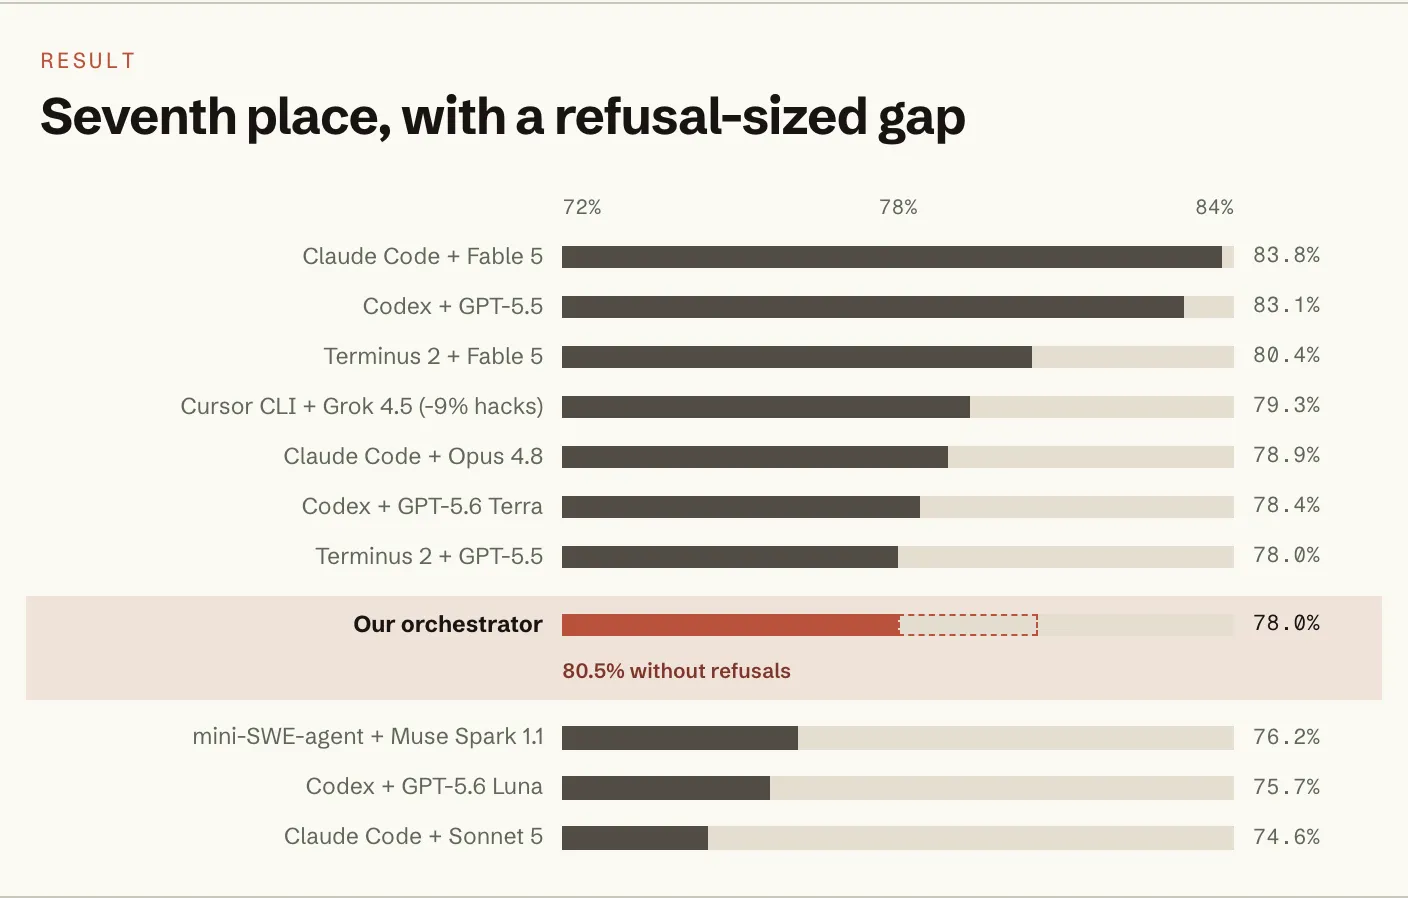
Four Claude models wired together in Claude Code: model refusals on delegated security tasks, seventh place, twice the cost of the top single-model run.
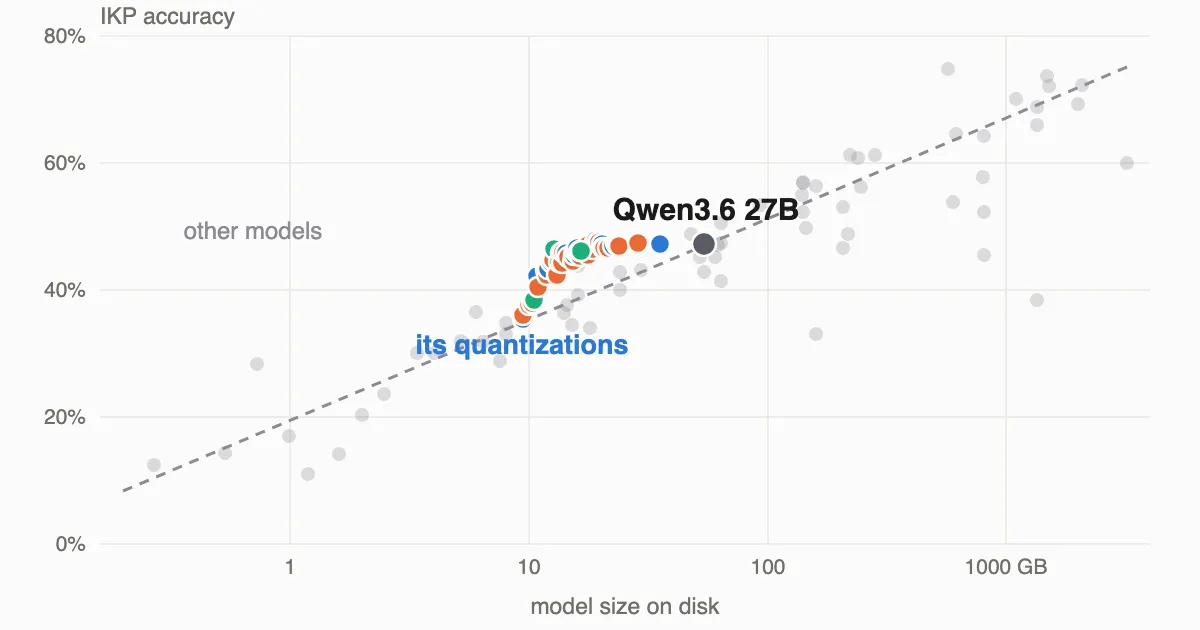
Quantization is a lossy compression, and factual knowledge is incompressible. We test Qwen3.6 27B GGUF quantizations from Hugging Face (by Unsloth and Bartowski) and llama.cpp on the Incompressible Knowledge Probes (IKP) benchmark.
We evaluate July 2026 fresh releases Kimi K3, Claude Opus 5, Grok 4.5, Gemini 3.6 Flash, and DeepSeek V4 Flash 0731 on Baba Is Bench, an LLM agent benchmark based on the puzzle game Baba Is You, comparing pass rate, speed, and cost with Claude Fable 5 and GPT-5.6.