Patterns worth fixing
Checked in every session, priced by what they waste.
- Context past 200k$6,784
- Cache rebuilt after a break$1,583
- Stopped turns$260
Fix "autoCompactWindow": 200000
Know where your AI coding spend goes
Your bill, split by project, person, task type, and model. Then the seats to cancel and the plans to upgrade.
A team you didn’t expect found a use for the tools.
The default model got smarter, and pricier.
The work ran hot for three weeks because you asked it to.
Every agent session, sized by what it cost and grouped by the work it did: features, investigations, reviews, fixes. Open a cluster to see the sessions behind it.
Explore the live demoEach dot is a session, sized by its cost.
Find your team's most expensive session for any filter, and see its details.
Pick a project, person, team, task type, agent or model. Quesma ranks its sessions by cost and opens each one.
Cost tools only find things to cut. Quesma also finds problems recurring across teams, and the skills, tools, and routines used in one part of the company but nowhere else.
Checked in every session, priced by what they waste.
Fix "autoCompactWindow": 200000
Projects by share of sessions past 200k. Start top right.
3 sessions make half of the $6,784 past 200k.
66% of the spend ran at high effort or above.
| Model | low | medium | high | xhigh | max |
|---|---|---|---|---|---|
| claude-opus-5-5 | $4,428$4.4k | $5,959$6.0k | $7$7 | ||
| gpt-6-astra | $56$56 | $2,267$2.3k | $1,761$1.8k | $1,377$1.4k | $70$70 |
| claude-fable-5-1 | $30$30 | $4,633$4.6k | $11$11 | $174$174 | |
| claude-opus-5 | $2,892$2.9k | ||||
| gpt-6.1-sol | $1,116$1.1k | $598$598 |
Find these patterns in your own team.
Quesma checks every session for patterns that waste money and shows what to change, with the saving.
Can coding agents find backdoors in compiled binaries using Ghidra and radare2?
We built training environments for difficult, multi-hour agent tasks. The work required reading full trajectories: prompts, tool calls, failures, retries, and results.
We audited Blitzy's 66.5% SWE-Bench Pro result, reviewing the environment, required changes, and final score.
Read the independent auditQuesma contributed to Terminal-Bench 3.0, a benchmark for testing agents on practical terminal tasks.
View the contributorsOpenAI cited our Baba Is Bench work while examining what makes agent evaluations succeed.
Read the citation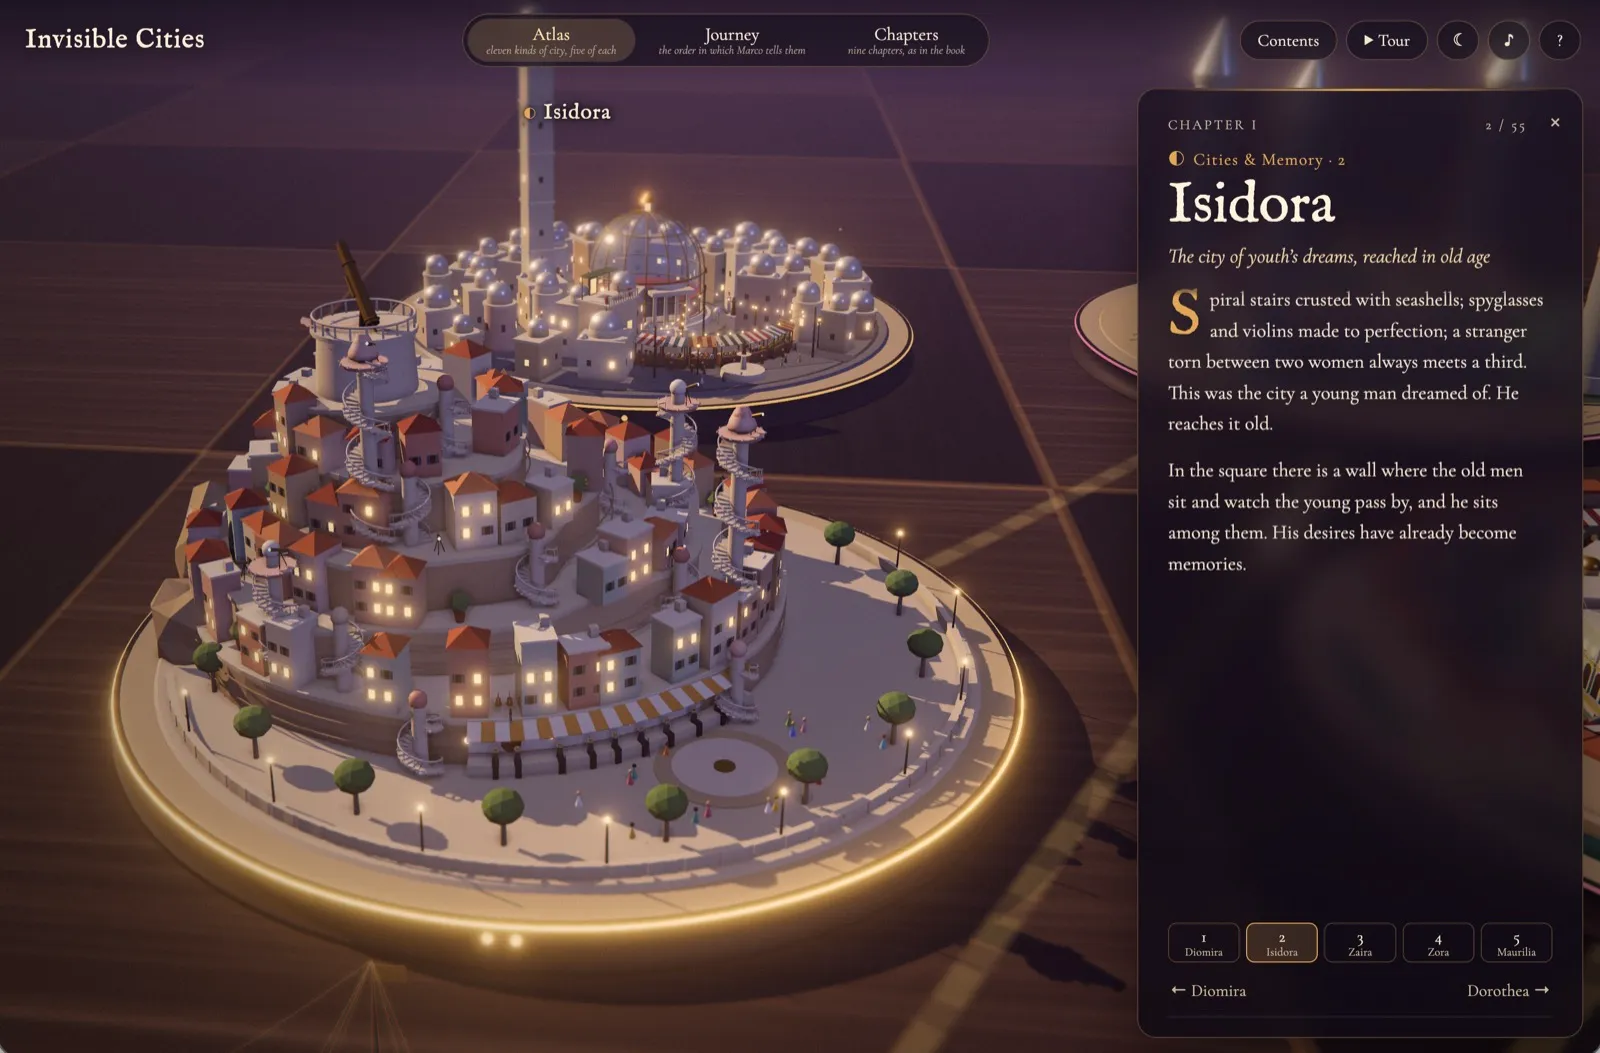 HN
Claude Opus 5.5 vs GPT-6 Astra one-shot Invisible Cities by Italo Calvino in Three.js: AI design, UX, data visualization and explorable explanations.
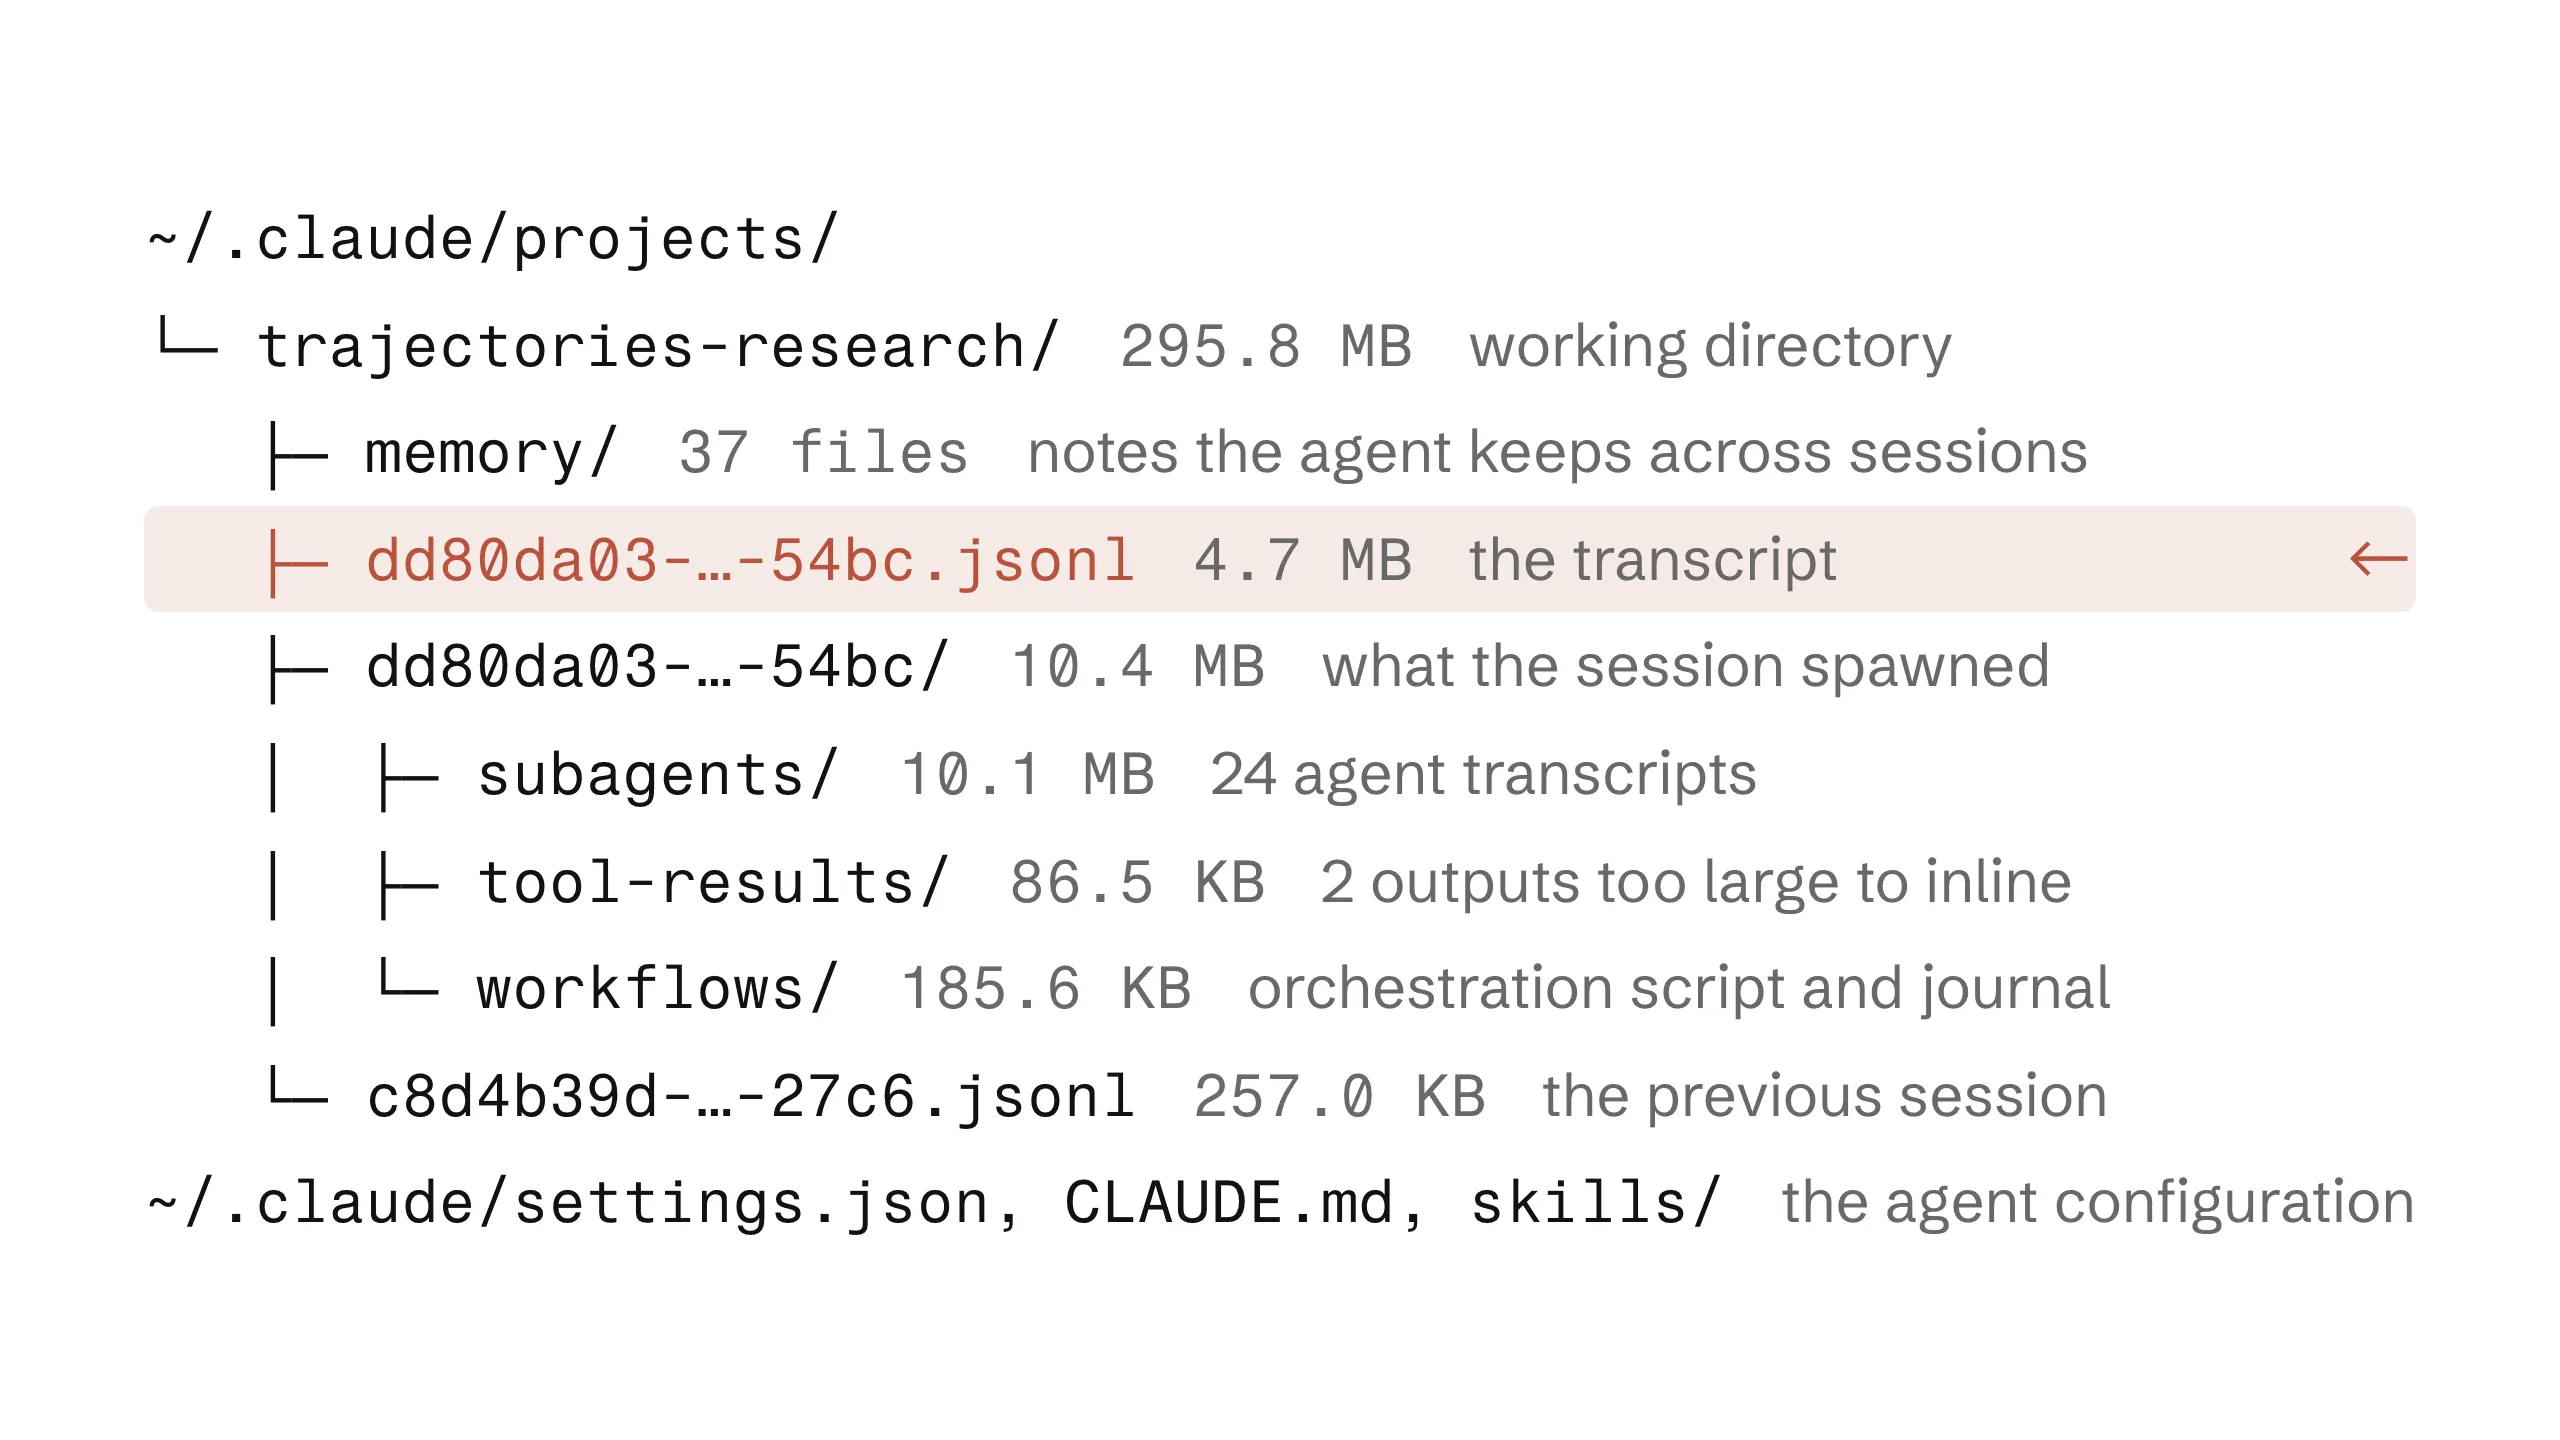
AI vendors collect every coding session they can, yet most teams discard their own. Quesma Shipper collects them into Amazon S3.
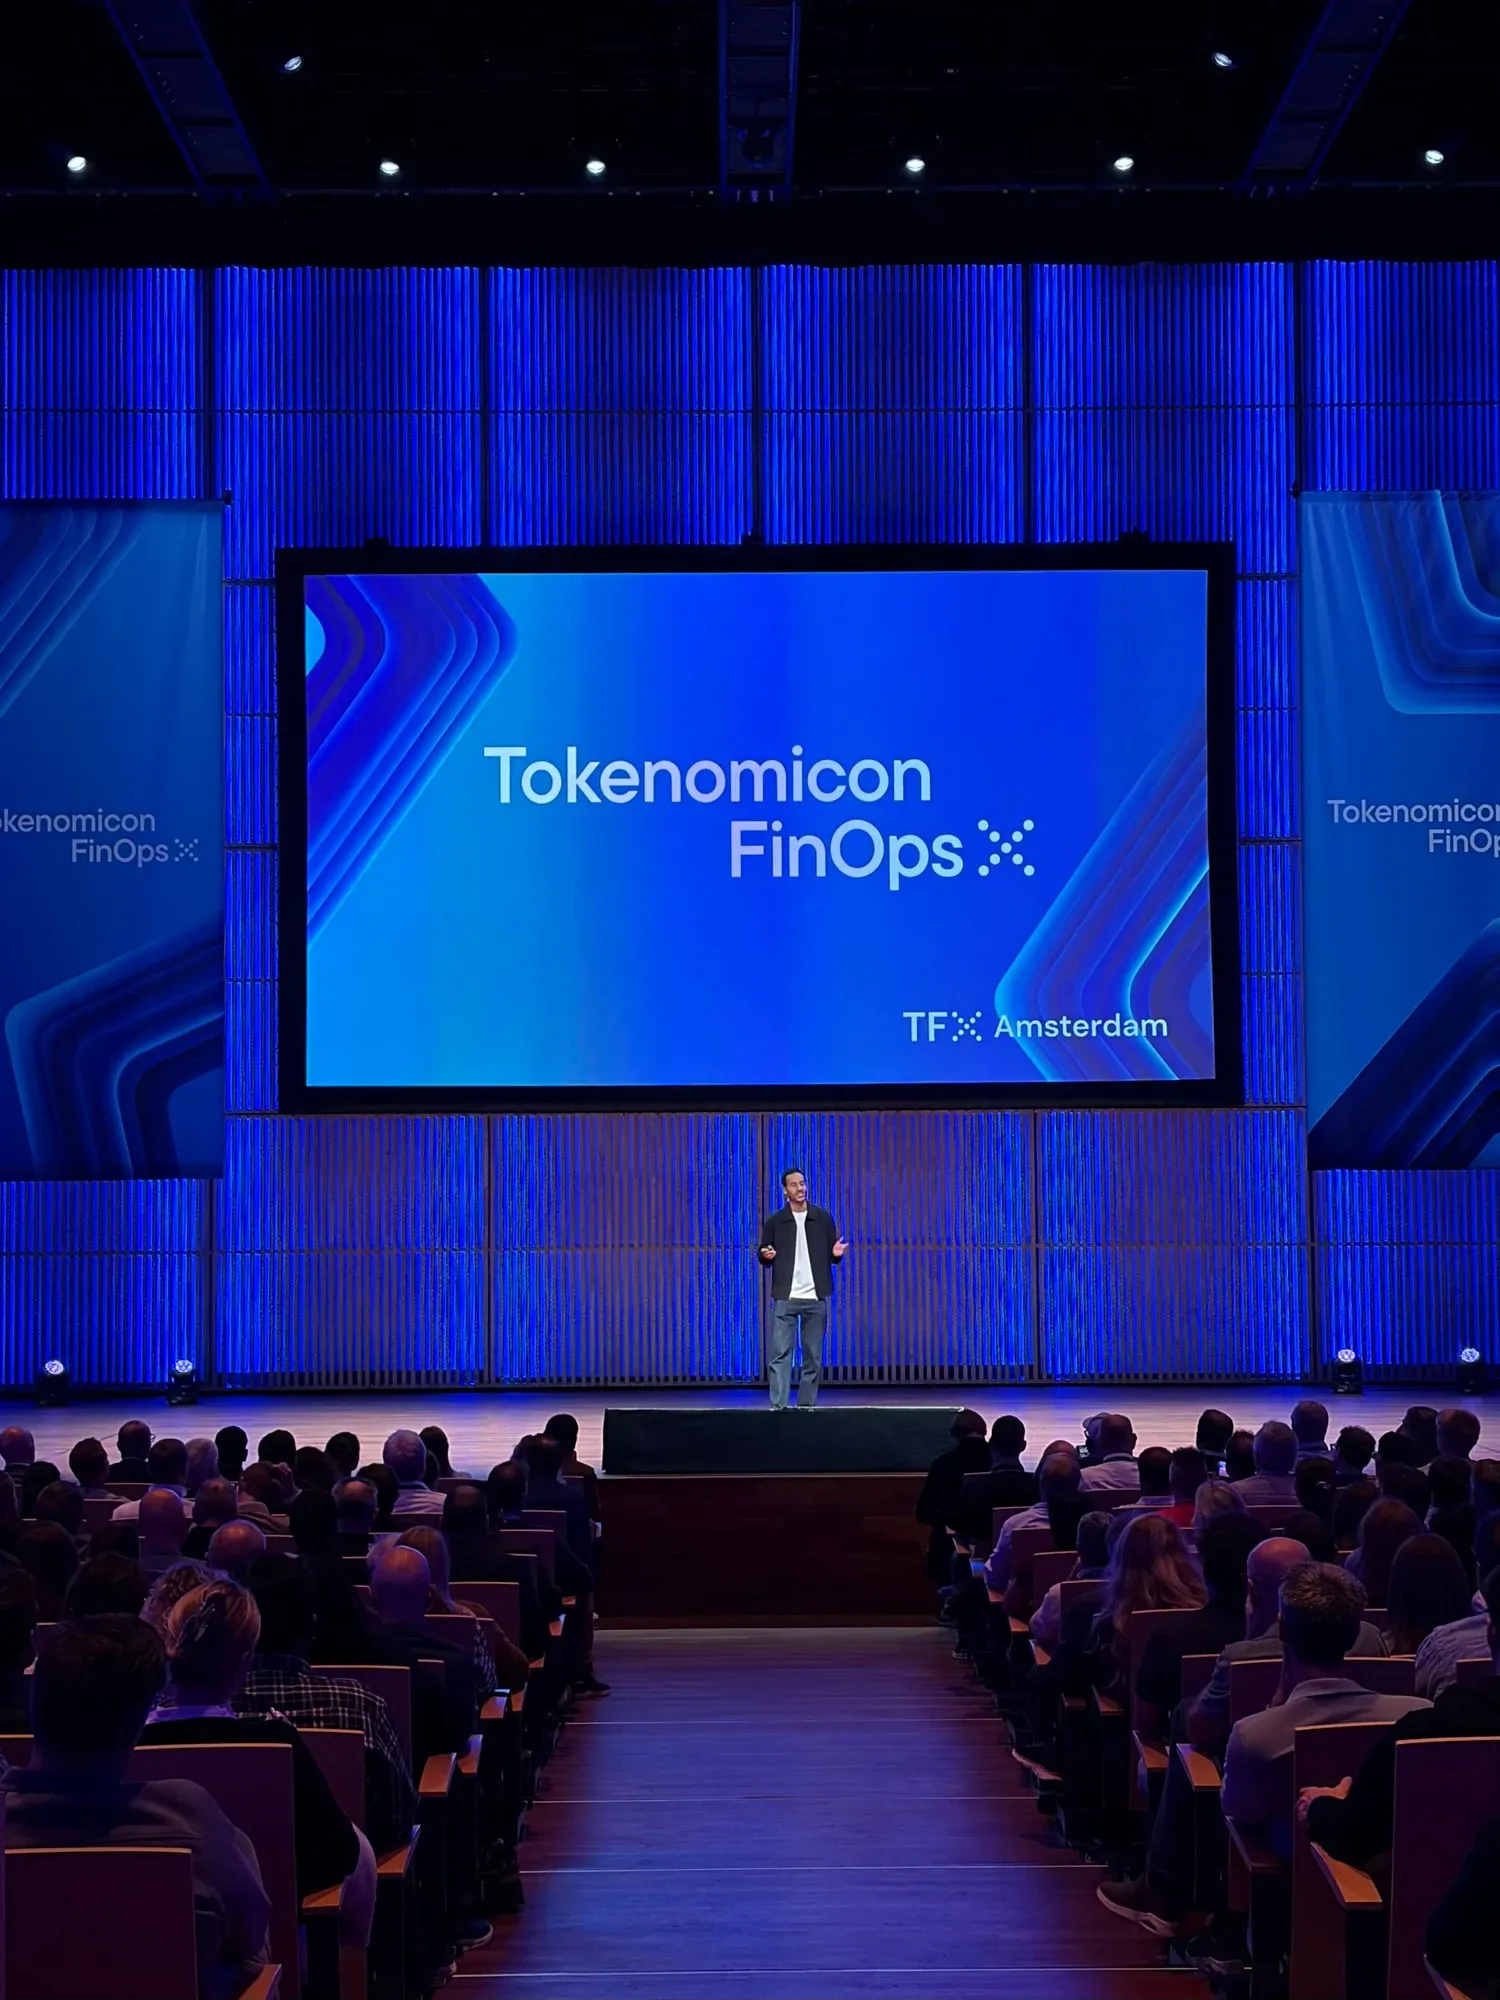
The Linux Foundation expands its FinOps work with a Tokenomics organization focused on AI spend. It held its first in-person conference in Amsterdam.
Early access opens soon. The open-source collector runs in your environment and the session data stays in your cloud. Contact us to be one of the first teams.